Case study
U.S. Bank Capital Research (2000-2025)
Built a research-grade data pipeline for U.S. commercial banks to study capital structure and cost of capital.
Overview
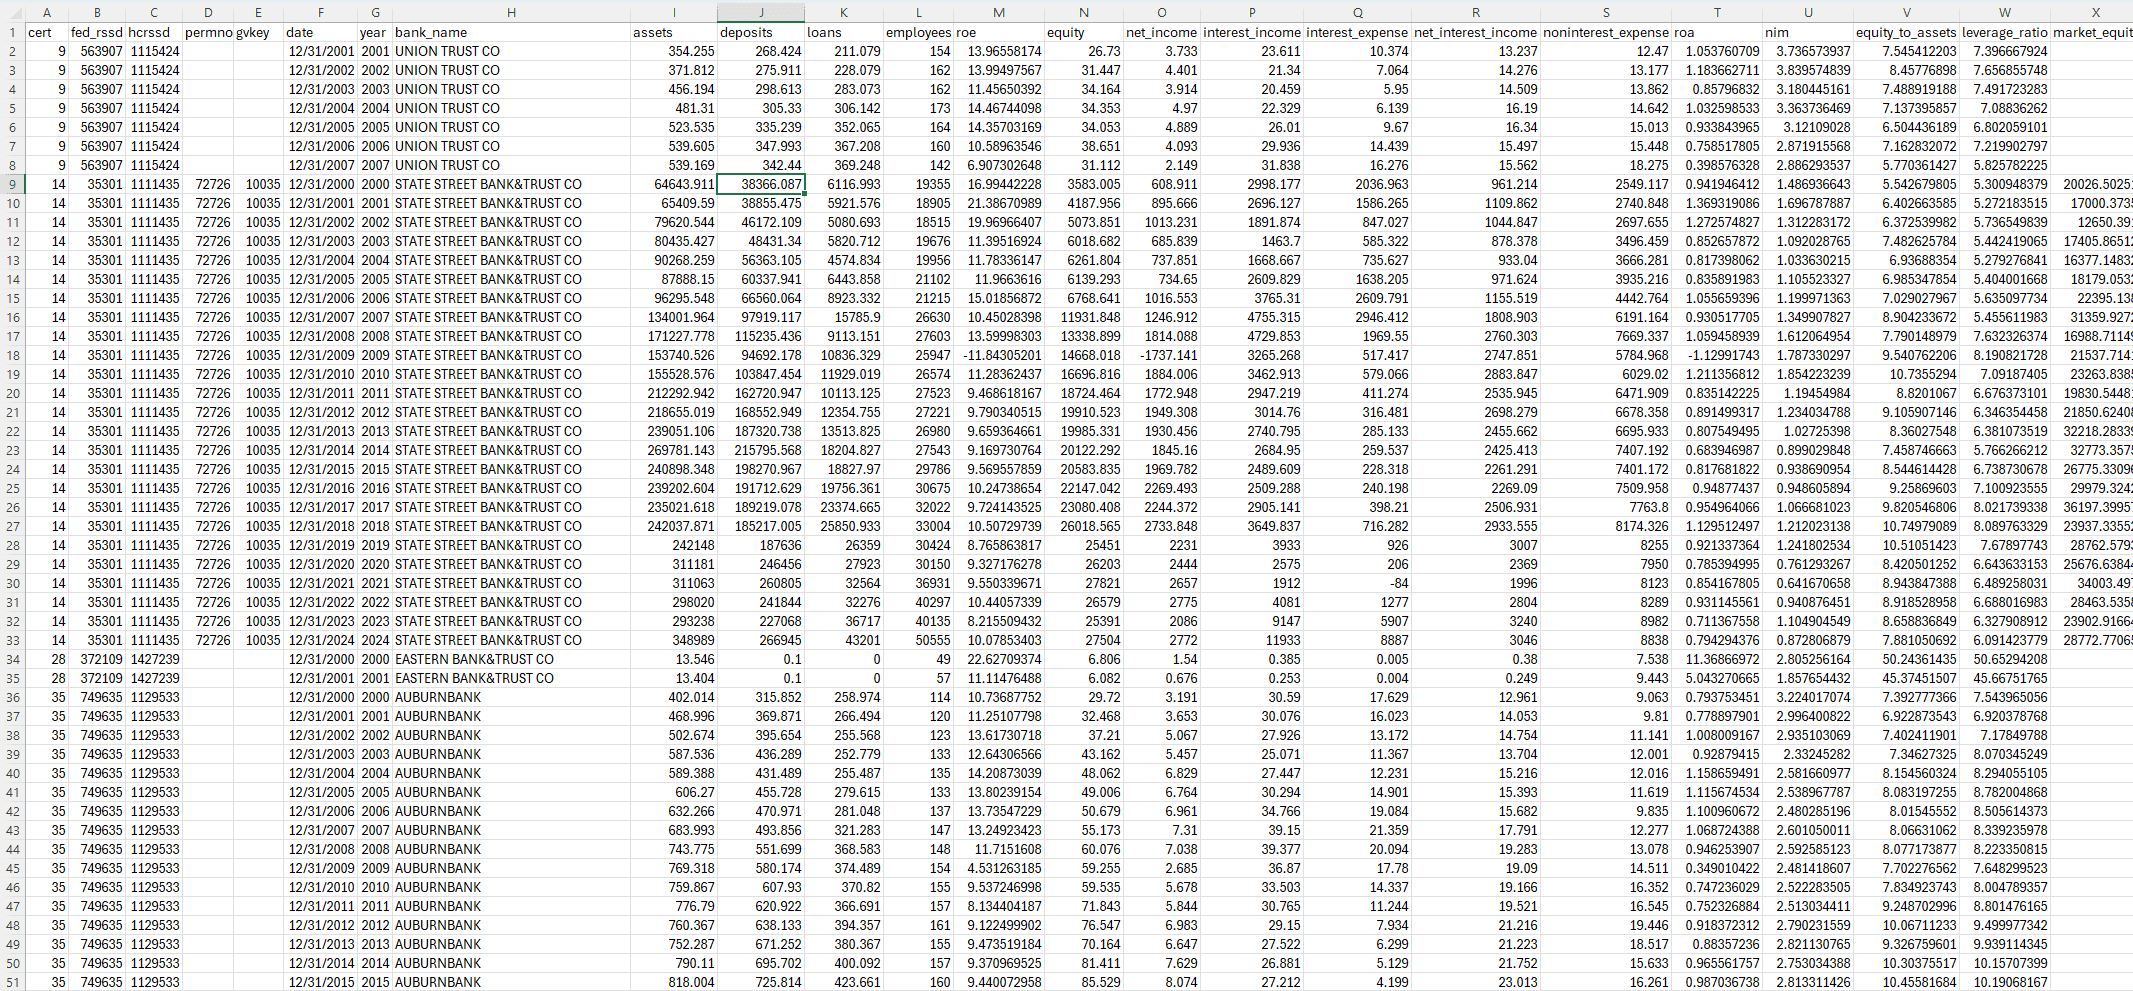
This project was completed as part of an academic Summer Research Scholarship focused on constructing a clean longitudinal dataset for all U.S. commercial banks from 2000 to 2025. I built Python ETL pipelines to ingest and structure data from FDIC, EDGAR, and CRSP, covering 176k+ observations across 11,000+ institutions. The work included designing identifier-linkage logic across FDIC CERT, CIK, GVKEY, and PERMNO, implementing quality assurance scripts to validate capital ratios, accounting identities, and time-series consistency, and engineering financial variables such as ROE, NIM, funding costs, and regulatory indicators. I also adopted and extended existing research code to estimate dynamic power-law distributions of U.S. bank assets, supporting analysis of cross-sectional mean reversion and idiosyncratic volatility across bank size groups. Due to research confidentiality, the full repository is private, but the system architecture and methodology reflect production-grade financial data platforms used in industry.